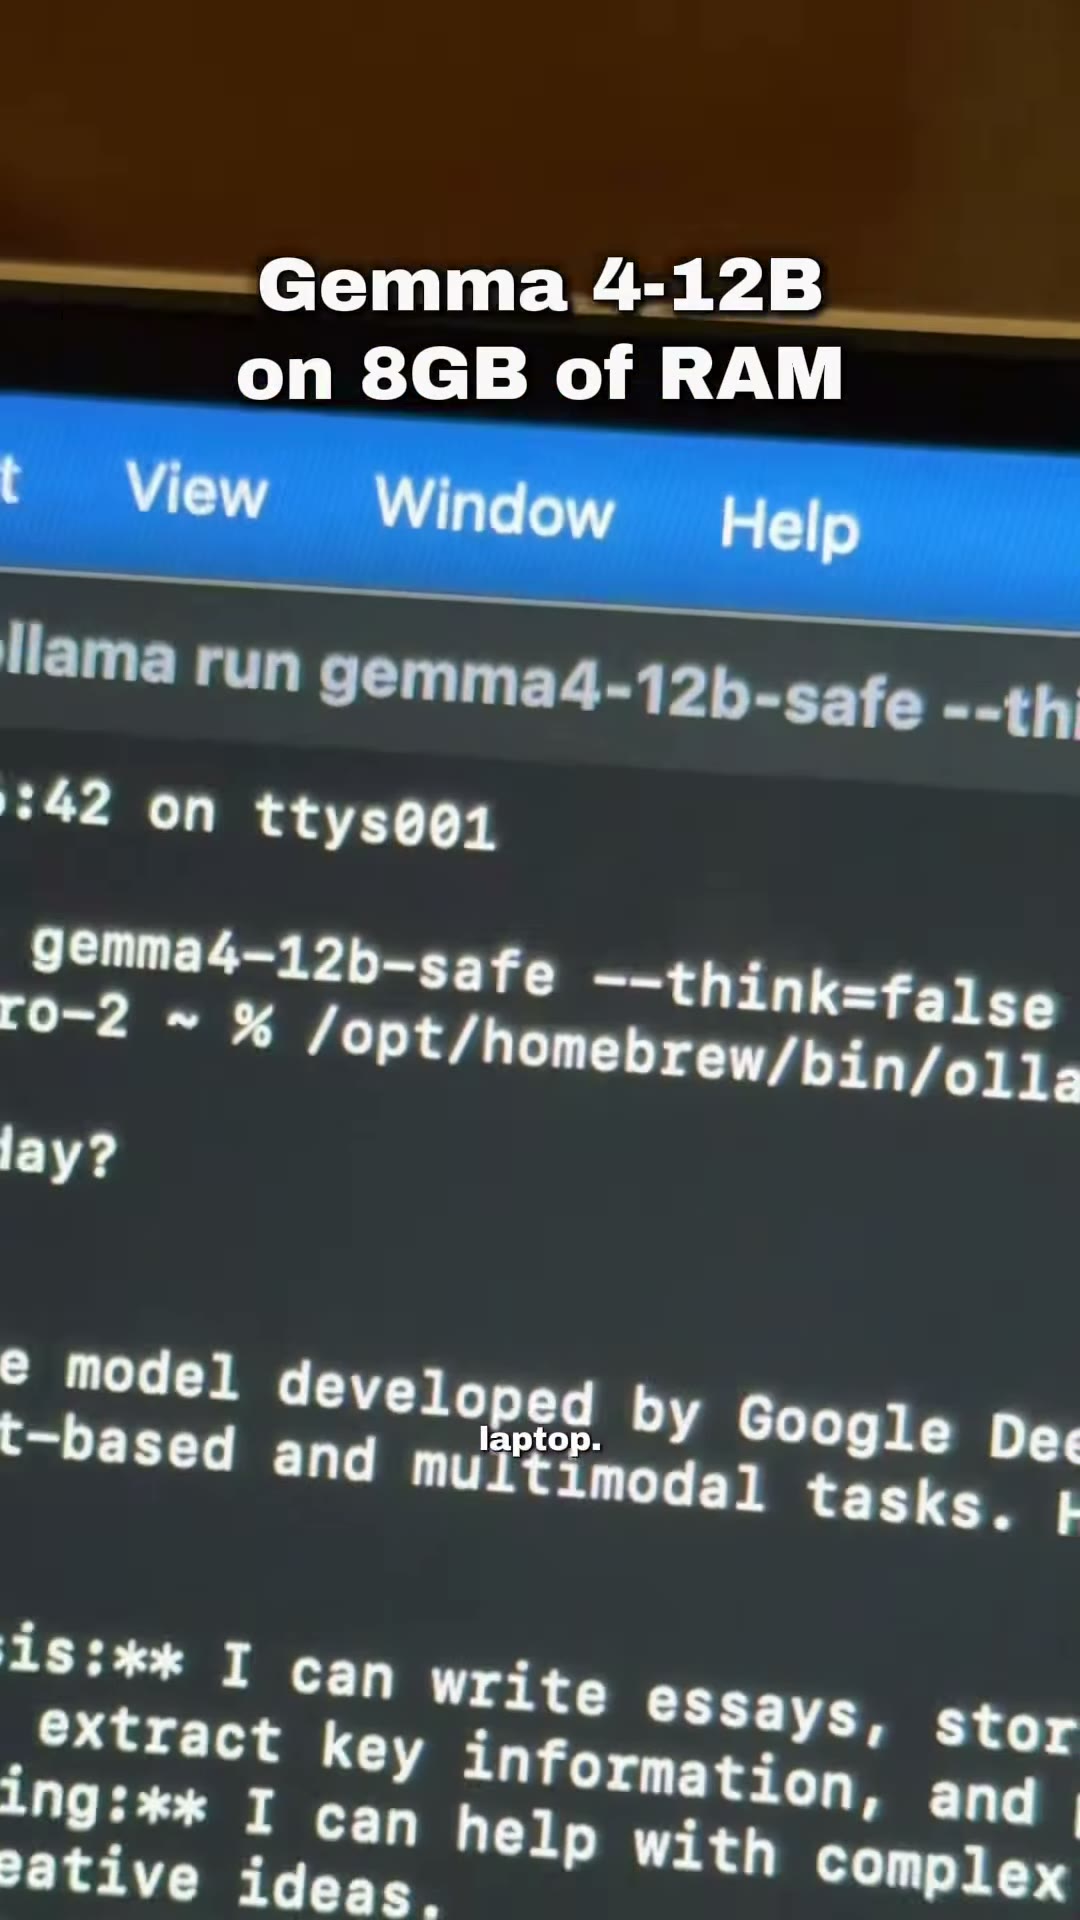
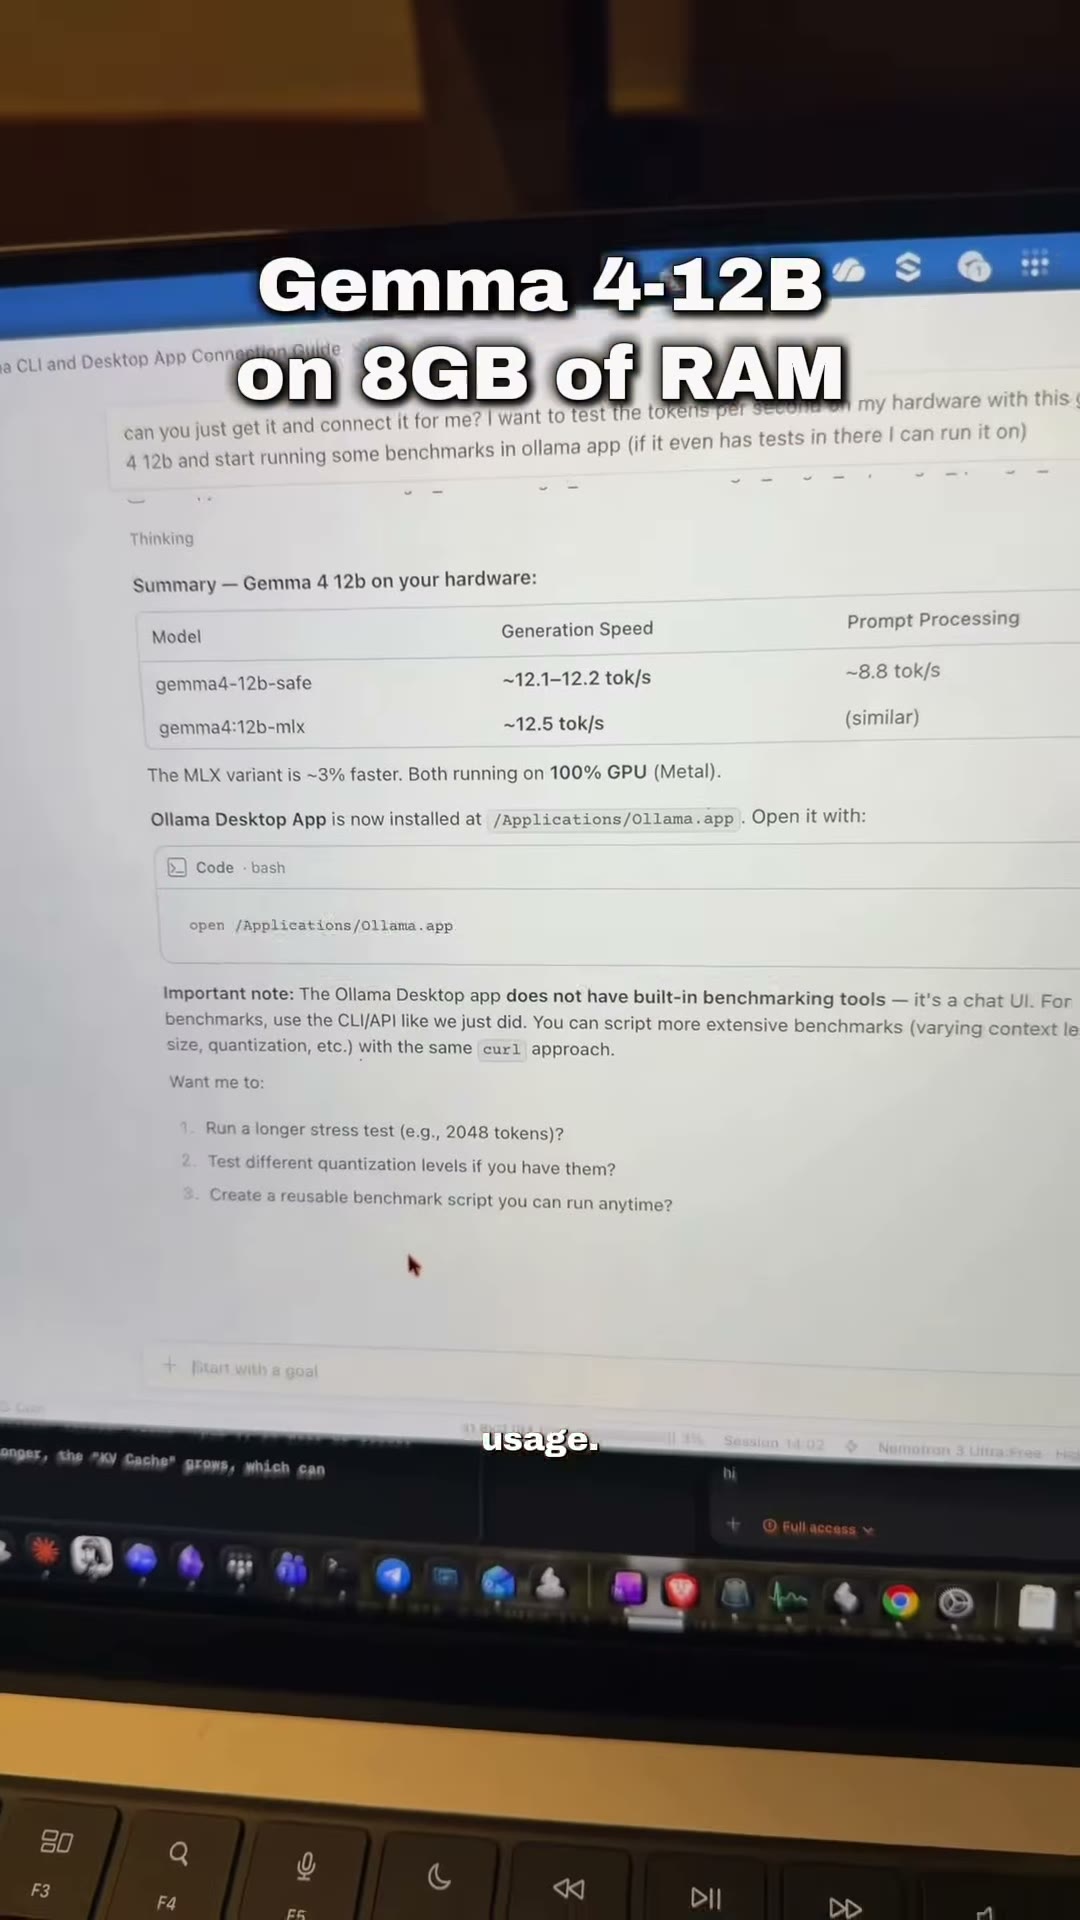
Creator runs Gemma 4 12B locally via Ollama on a laptop, benchmarking tokens/sec and tool-calling ability.
On prem on prem on prem
#google #gemma4 #ai
Gemma 4-12B on 8GB of RAM this
Gemma 4-12B on 8GB of RAM View Window Help llama run gemma4-12b-safe --thi :42 on ttys001 gemma4-12b-safe --think=false ro-2 ~ % /opt/homebrew/bin/olla lay? e model developed by Google Dee t-based and multimodal tasks. H laptop. sis:** I can write essays, stor extract key information, and p ing:** I can help with complex eative ideas,
Gemma 4-12B on 8GB of RAM apparently
Gemma 4-12B on 8GB of RAM a CLI and Desktop App Connection Guide can you just get it and connect it for me? I want to test the tokens per second on my hardware with this g 4 12b and start running some benchmarks in ollama app (if it even has tests in there I can run it on) Thinking Summary — Gemma 4 12b on your hardware: Model Generation Speed Prompt Processing gemma4-12b-safe ~12.1–12.2 tok/s ~8.8 tok/s gemma4:12b-mlx ~12.5 tok/s (similar) The MLX variant is ~3% faster. Both running on 100% GPU (Metal). Ollama Desktop App is now installed at /Applications/Ollama.app. Open it with: Code · bash open /Applications/Ollama.app Important note: The Ollama Desktop app does not have built-in benchmarking tools — it's a chat UI. For benchmarks, use the CLI/API like we just did. You can script more extensive benchmarks (varying context le size, quantization, etc.) with the same curl approach. Want me to: 1. Run a longer stress test (e.g., 2048 tokens)? 2. Test different quantization levels if you have them? 3. Create a reusable benchmark script you can run anytime? usage. hi Start with a goal Session 14:02 Nemotron 3 Ultra:Free Full access onger, the "KV Cache" grows, which can F3 F4 F5
Gemma 4-12B on 8GB of RAM 12.1-12.5 tok/s great.
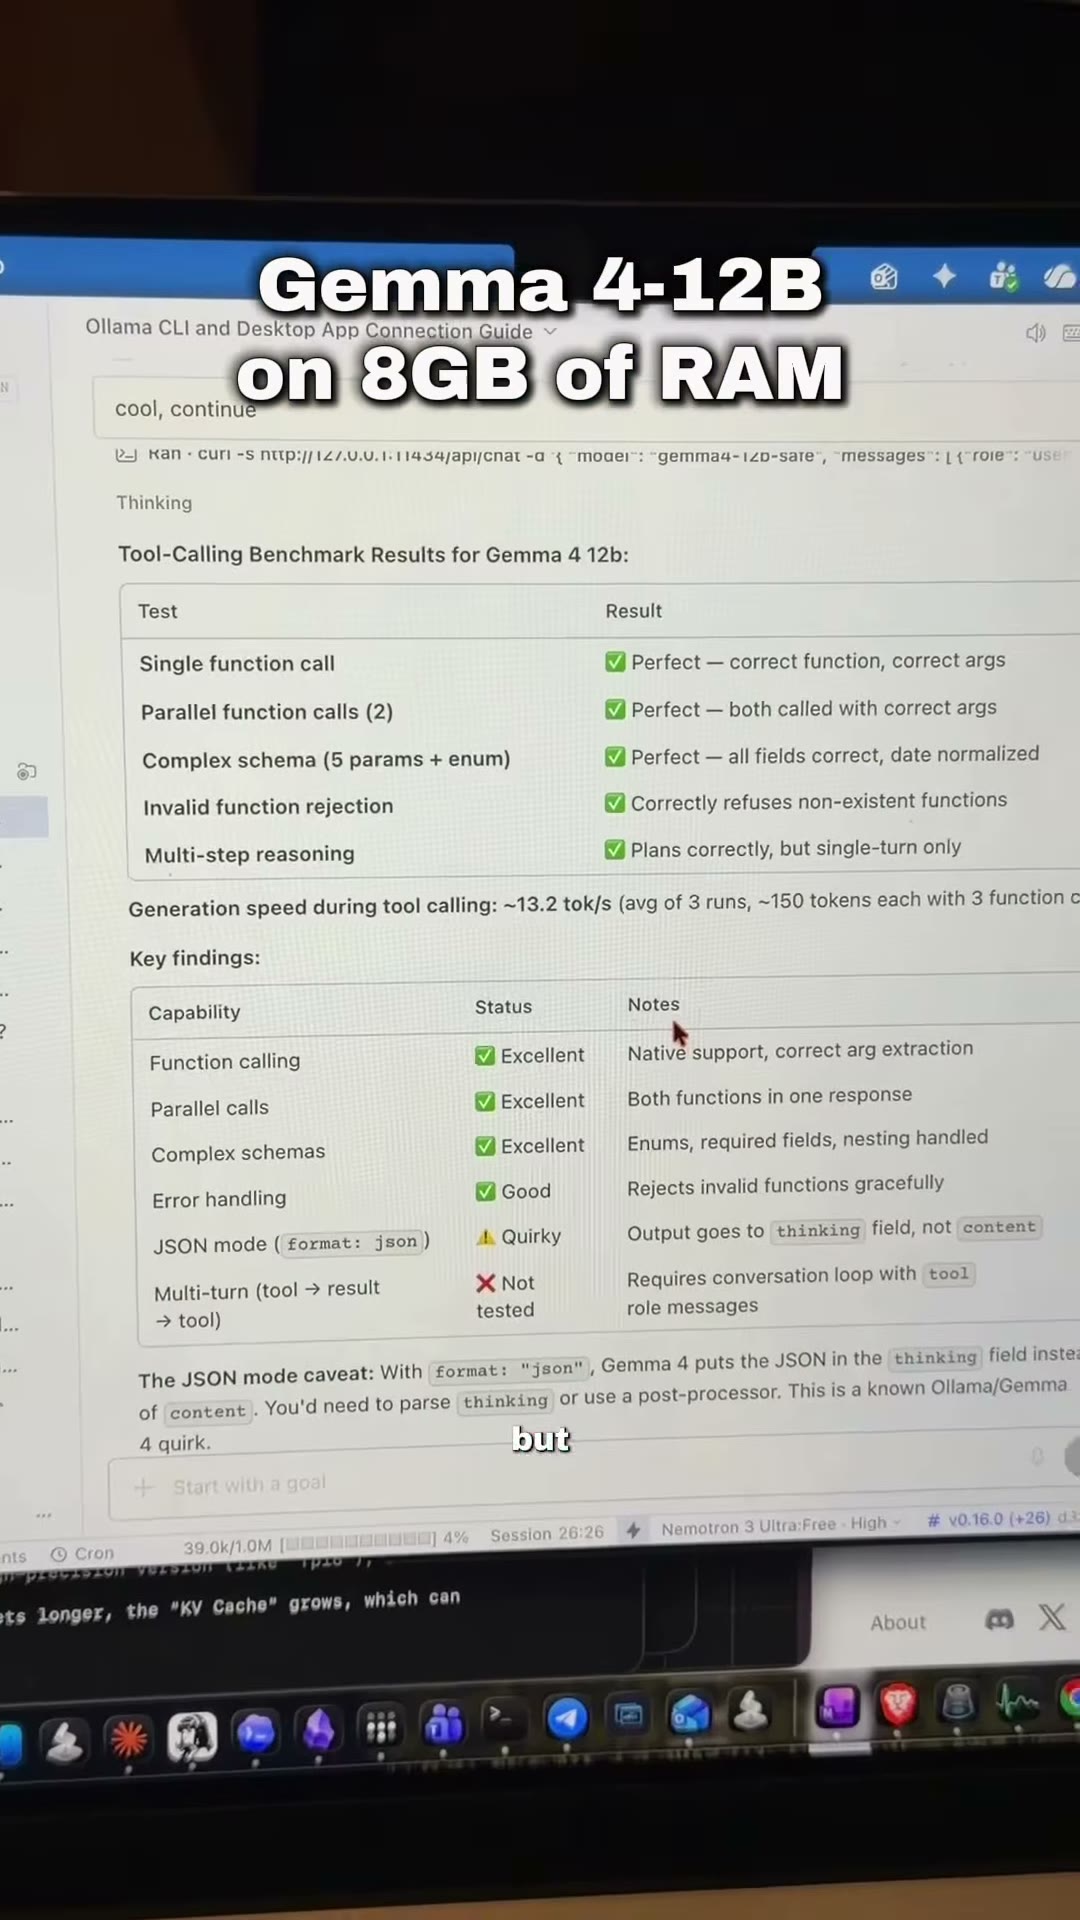
Gemma 4-12B on 8GB of RAM Ollama CLI and Desktop App Connection Guide cool, continue Ran · curl -s http://127.0.0.1:11434/api/chat -d { "model": "gemma4-12b-safe", "messages": [{"role": "user Thinking Tool-Calling Benchmark Results for Gemma 4 12b: Test Result Single function call ✅ Perfect — correct function, correct args Parallel function calls (2) ✅ Perfect — both called with correct args Complex schema (5 params + enum) ✅ Perfect — all fields correct, date normalized Invalid function rejection ✅ Correctly refuses non-existent functions Multi-step reasoning ✅ Plans correctly, but single-turn only Generation speed during tool calling: ~13.2 tok/s (avg of 3 runs, ~150 tokens each with 3 function c Key findings: Capability Status Notes Function calling ✅ Excellent Native support, correct arg extraction Parallel calls ✅ Excellent Both functions in one response Complex schemas ✅ Excellent Enums, required fields, nesting handled Error handling ✅ Good Rejects invalid functions gracefully JSON mode (format: json) ⚠️ Quirky Output goes to thinking field, not content Multi-turn (tool → result → tool) ❌ Not tested Requires conversation loop with tool role messages The JSON mode caveat: With format: "json", Gemma 4 puts the JSON in the thinking field instead of content. You'd need to parse thinking or use a post-processor. This is a known Ollama/Gemma 4 quirk. but Start with a goal 39.0k/1.0M 4% Session 26:26 Nemotron 3 Ultra:Free · High # v0.16.0 (+26) ets longer, the "KV Cache" grows, which can About
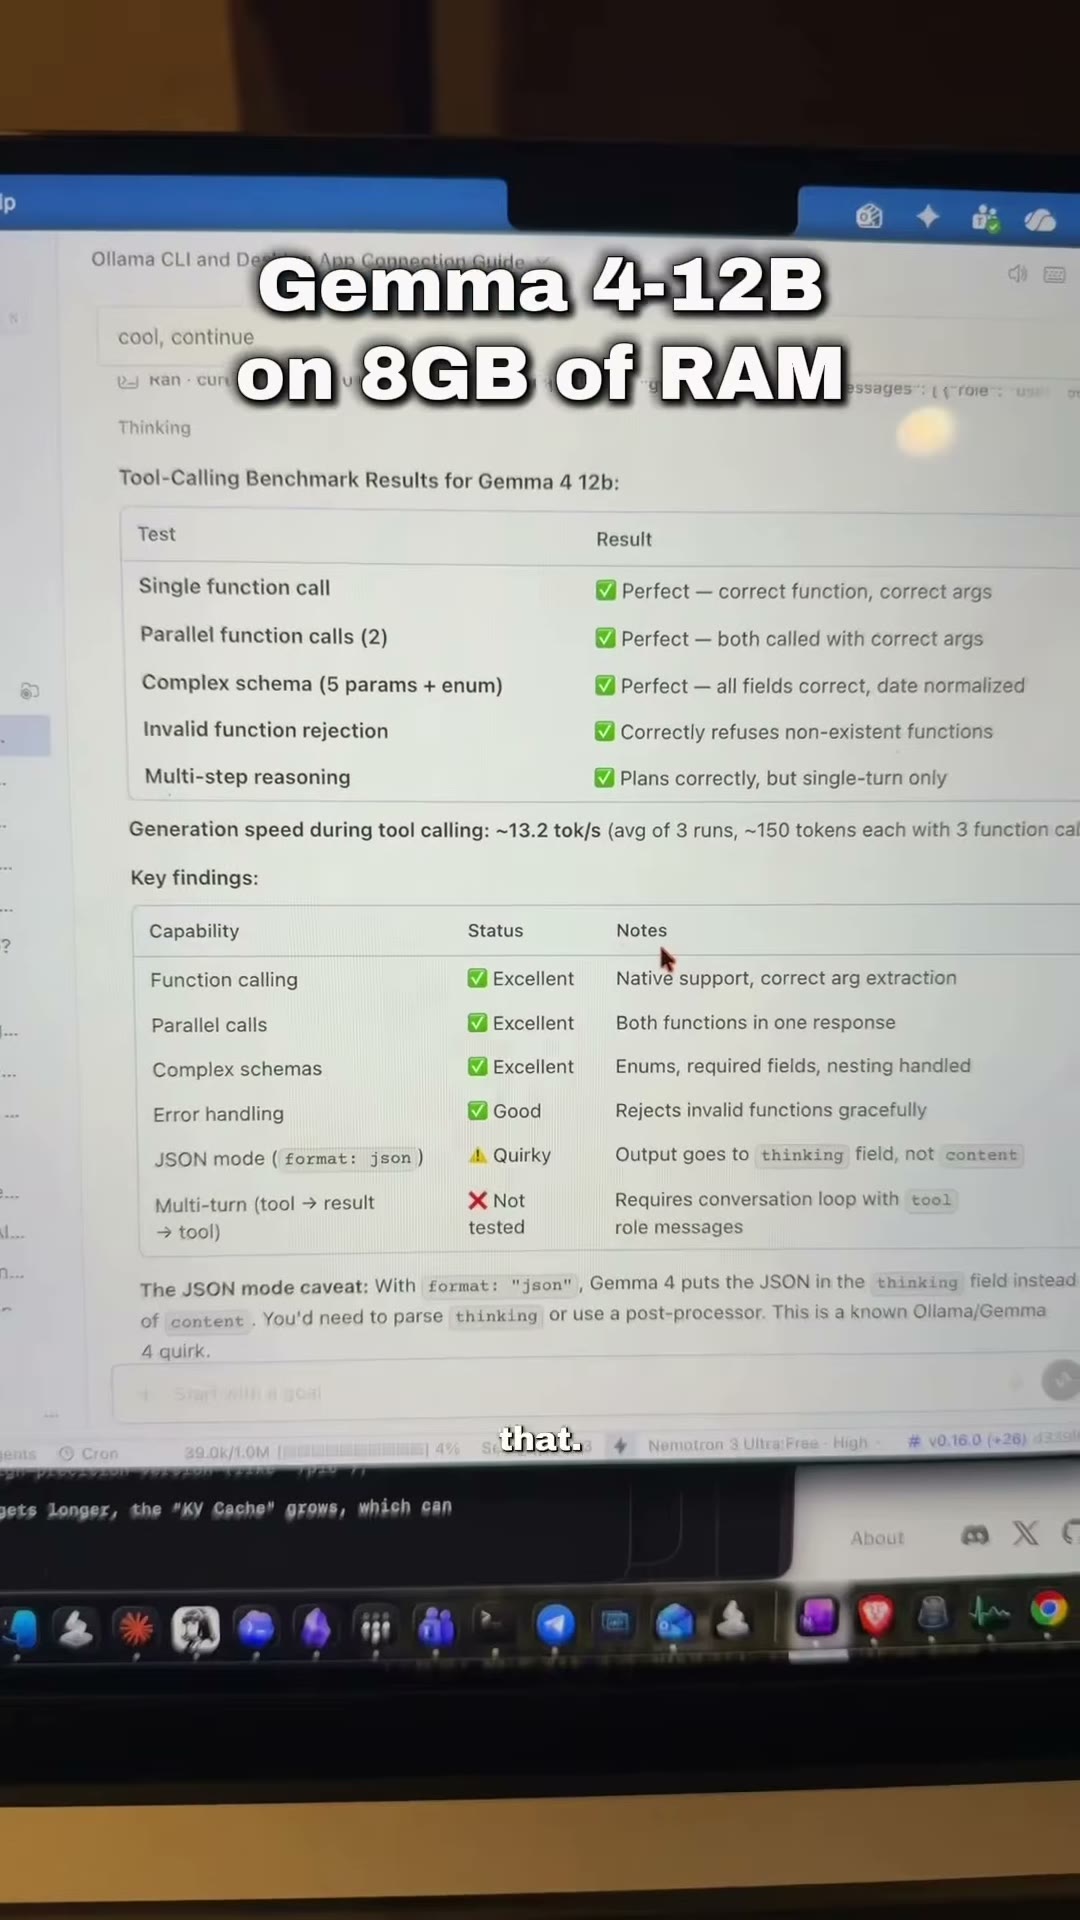
Gemma 4-12B on 8GB of RAM Ollama CLI and De App Connection Guide cool, continue Ran · curl essages": [{"role": use Thinking Tool-Calling Benchmark Results for Gemma 4 12b: Test Result Single function call ✅ Perfect — correct function, correct args Parallel function calls (2) ✅ Perfect — both called with correct args Complex schema (5 params + enum) ✅ Perfect — all fields correct, date normalized Invalid function rejection ✅ Correctly refuses non-existent functions Multi-step reasoning ✅ Plans correctly, but single-turn only Generation speed during tool calling: ~13.2 tok/s (avg of 3 runs, ~150 tokens each with 3 function cal Key findings: Capability Status Notes Function calling ✅ Excellent Native support, correct arg extraction Parallel calls ✅ Excellent Both functions in one response Complex schemas ✅ Excellent Enums, required fields, nesting handled Error handling ✅ Good Rejects invalid functions gracefully JSON mode (format: json) ⚠️ Quirky Output goes to thinking field, not content Multi-turn (tool → result → tool) ❌ Not tested Requires conversation loop with tool role messages The JSON mode caveat: With format: "json", Gemma 4 puts the JSON in the thinking field instead of content. You'd need to parse thinking or use a post-processor. This is a known Ollama/Gemma 4 quirk. that. 39.0k/1.0M 4% Nemotron 3 Ultra:Free · High # v0.16.0 (+26) gets longer, the "KV Cache" grows, which can About
Gemma 4-12B on 8GB of RAM i
Why am I on the ground? Well, my codex is currently getting my Olama with Gemma 412b working, which is like one of the craziest advancements in local models. I talked about this a while ago when Gemma 4 first came out. This Edge Compute local model setup will be nuts. Like, I don't think people can tell what's coming right now, especially with how far we've gotten with local models or Edge Compute on your phone or your laptop, Gemma 412b. Apparently, it's really good at toolcalling, so if I put it in one of my programs that I have on here, I'm gonna test it, see how good it is. I'm using my Hermes now that my codex is out of usage. All right, not great. I was expecting a lot more. But, hey, look at that. Well, look, it's pretty sweet. It's pretty, pretty good. I really don't care how fast this one is, just as long as it's capable. So, I don't know, pretty funky. Little post more when I start using it a lot more.
scraped.media
derived.classifier
derived.classifier
scraped.caption
derived.classifier
derived.classifier
user.note
derived.audio_transcript
derived.keyframe_ocr